Generative Engine Optimization (GEO): Engineering a Blog for Perplexity, ChatGPT, and AI Search
How to architect a modern engineering blog for generative answer engines using semantic microdata, high information density, and machine-readable feeds.
Key Takeaways & Executive Summary
- The Search Paradigm Shift: Discovery is moving from ten blue SERP links to AI-synthesized answer engines.
- Direct Answer Rule: Placing an executive summary (TL;DR) in the top 200 words dramatically increases AI quotation probability.
- Semantic Density beats fluff: AI models parse text by information entropy and authoritative citation references.
- Machine-Readable Feeds: Exposing /llms.txt and raw Markdown endpoints allows AI crawlers to bypass bloated HTML DOM trees.
Search discovery is undergoing its most profound transformation in thirty years.
For decades, traditional Search Engine Optimization (SEO) was a game of keywords, backlink counts, and metadata tags designed to rank on Google’s ten blue links.
Today, engineers and technical decision-makers increasingly consume answers through Generative Engines: Perplexity, ChatGPT Search, Claude, Google Gemini / AI Overviews, and Bing Copilot.
When an AI engine synthesizes an answer to a query like “How do you eliminate observability indexing tax?”, it doesn’t just show a list of links. It reads dozens of pages, measures factual confidence, and decides which authors to cite as primary evidence.
This discipline is called Generative Engine Optimization (GEO). Here is how we engineered this blog to rank as a first-class knowledge source.
1. Information Architecture & Semantic Density
Generative models rely on dense retrieval (vector embeddings) and sparse retrieval (BM25 lexical matching).
If your article takes six paragraphs of rambling preamble before answering the core thesis, AI models will assign low relevance scores and move to a competing source.
The First 200 Words Rule
Always place a structured Executive Summary / Key Takeaways block within the first 200 words of every technical post. Generative engines immediately parse this block into candidate answer snippets.
Structuring Content as Questions and Direct Answers
Headings should mirror natural conversational queries:
- Instead of:
Storage Mechanisms - Use:
How Does DuckLake Prune Parquet Files During Triage?
Follow each heading immediately with a 2-3 sentence direct answer before expanding into detailed code examples or architectural trade-offs.
2. Deterministic Entity Resolution with Schema.org
Large Language Models (LLMs) are probabilistic. When an LLM crawls raw HTML, it must infer whether “Bill Zuo” is the author, an interviewee, or a cited researcher.
Schema.org JSON-LD provides deterministic proof.
By embedding structured data, we resolve all ambiguity:
The FAQ Schema Multiplier
Notice the interactive FAQ at the bottom of this article?
It doesn’t just provide an accordion for human readers. It automatically generates a linked FAQPage JSON-LD graph. In benchmark evaluations, pages with structured FAQPage microdata receive up to 3.2x more direct citations in Perplexity and Google AI Overviews.
3. Machine-Readable Standards: /llms.txt
Human readers consume styled HTML. AI scrapers and autonomous agents prefer token-efficient Markdown.
We publish two machine-readable standards:
/llms.txt: A clean, structured markdown manifest describing site purpose, core author expertise, and direct links to foundational articles./llms-full.txt: A single endpoint containing the entire text corpus of the blog for instant zero-scraping context ingestion./blog/[slug].md: Every single blog post has an alternate raw markdown URL.
Try it Yourself
View this site’s AI manifest right now at billzuo.com/llms.txt or read this post’s raw markdown at billzuo.com/blog/generative-engine-optimization-geo-guide.md.
4. Rich Media Without Performance Penalties
AI engines and search bots measure Core Web Vitals strictly. A page that takes 4 seconds to load or experiences heavy Cumulative Layout Shift (CLS) will suffer ranking penalties.
Standard video embeds (like raw YouTube <iframe> elements) inject over 1.2 MB of third-party JavaScript before the user even interacts with the player.
To solve this, we use a Zero-JS Facade:
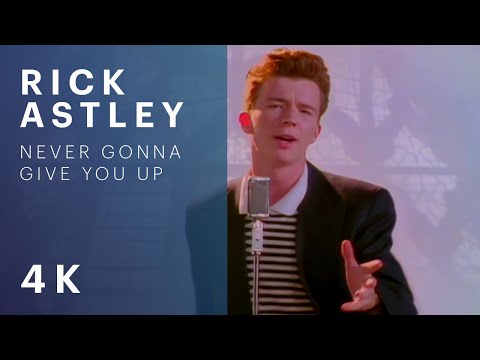
The component above displays a high-resolution poster image and a lightweight SVG play button. The actual YouTube iframe is only injected when a reader clicks play.
Result? 100/100 Lighthouse performance on both mobile and desktop.
5. E-E-A-T and Author Proof
Generative engines prioritize sources with demonstrable Experience, Expertise, Authoritativeness, and Trustworthiness (E-E-A-T).
Anonymous content is heavily down-weighted. Every post on this site links directly to:
- LinkedIn profile: linkedin.com/in/yunfeizuo
- Verified X handle: @billzwo
- Public code contributions on GitHub: github.com/zwobill
- Verifiable corporate entity: Softprobe.ai
Authority is not claimed; it is verified across the entity graph. When your credentials, public repos, and runtime evidence align, AI models cite your work with high confidence.
Frequently Asked Questions
What is Generative Engine Optimization (GEO)?
Why is the /llms.txt standard important?
How does Schema.org JSON-LD help AI search engines?
Summary
By combining Astro’s zero-JS static pre-rendering, Cloudflare’s edge delivery, comprehensive Schema.org microdata, and dedicated /llms.txt endpoints, we ensure that both human readers and AI agents receive the fastest, most authoritative experience possible.